
All examples · Example 15 of 34
Range Bar: Dosing Windows
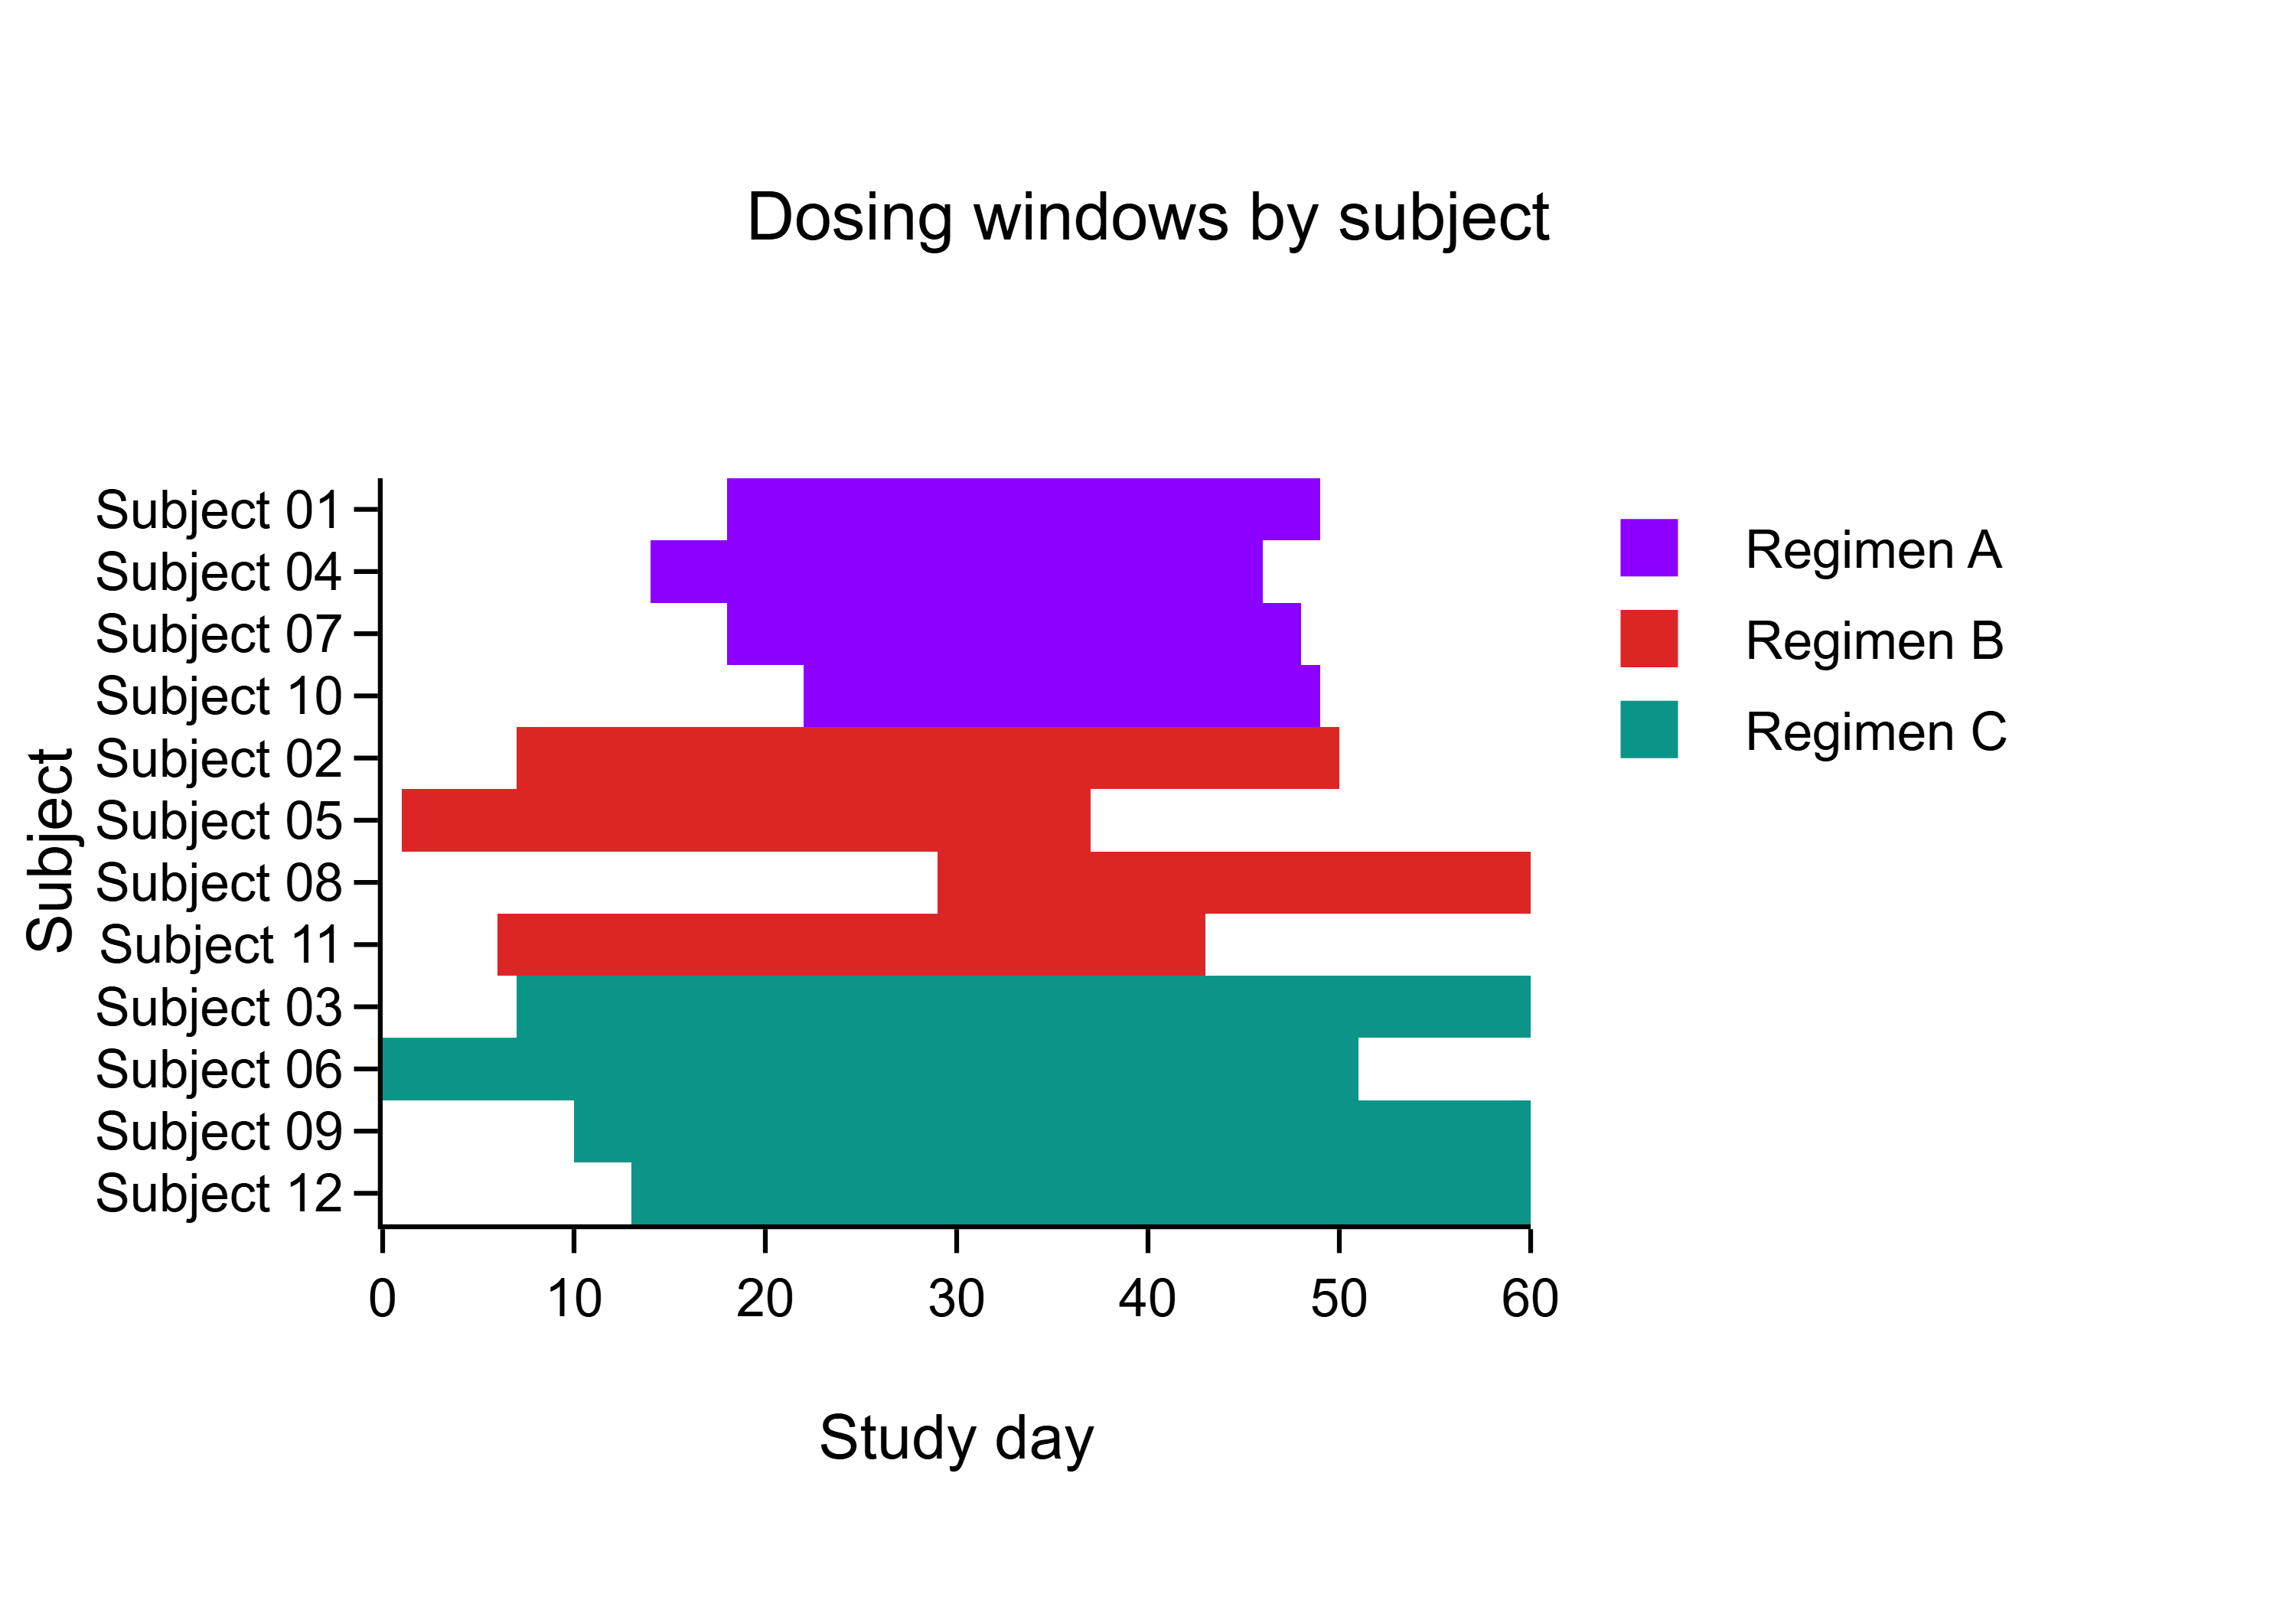
Dosing window (start to end study day) for each of 12 subjects, coloured by regimen.

Key findings
- Dosing windows differ by regimen: ANOVA F = 70.13, p = 3.2 × 10⁻⁶.
- With only 4 subjects per regimen, Kruskal–Wallis gives p = 0.007 and rank tests cannot reach small p-values at this n: the design, not the data, limits them.
- Dixon's Q is included in the outlier screen because it is built for exactly this sample size (3–30).
Descriptive statistics
Location, spread and shape for every group — the first thing to read before choosing a test. Skewness near 0 and excess kurtosis near 0 are what a normal distribution looks like.
| Group | n | Mean | SD | SEM | Median | Q1 – Q3 | Min – Max | Skewness | Excess kurtosis |
|---|---|---|---|---|---|---|---|---|---|
| Regimen A | 4 | 30 | 2.16 | 1.08 | 30.5 | 29.25 – 31.25 | 27 – 32 | -1.19 | 1.5 |
| Regimen B | 4 | 39.25 | 3.304 | 1.652 | 39 | 36.75 – 41.5 | 36 – 43 | 0.229 | -3.87 |
| Regimen C | 4 | 53 | 2.708 | 1.354 | 52 | 51.75 – 53.25 | 51 – 57 | 1.81 | 3.48 |
LabTools call
stats.describelabtools stats describe --groups @groups.json
The same method is available as an MCP tool (stats_describe) and from the desktop app's statistics panel.
Normality
Three tests of the same question — could these values come from a normal distribution? Shapiro–Wilk has the best power at bench sample sizes, Anderson–Darling is more sensitive in the tails, and Kolmogorov–Smirnov (Lilliefors-corrected) is included for comparability with older papers. A significant p means normality is rejected.
| Group | n | Shapiro–Wilk W | p | K–S D | p | Verdict |
|---|---|---|---|---|---|---|
| Regimen A | 4 | 0.9271 | 0.58 | 0.25 | 0.51 | Consistent with normal |
| Regimen B | 4 | 0.9157 | 0.51 | 0.2521 | 0.49 | Consistent with normal |
| Regimen C | 4 | 0.7729 | 0.062 | 0.394 | 0.030 | Normality rejected |
LabTools calls (2)
stats.normalitylabtools stats normality --groups @groups.json --method shapiro-wilk
stats.normalitylabtools stats normality --groups @groups.json --method kolmogorov-smirnov
The same method is available as an MCP tool (stats_normality) and from the desktop app's statistics panel.
LabTools notes
- Group 'Regimen A' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
- Group 'Regimen B' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
- Group 'Regimen C' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
- Group 'Regimen C' rejects normality (p = 0.0295); prefer a rank-based test.
Equal variances
Student's t and one-way ANOVA assume every group has the same spread. LabTools' Levene test uses deviations from the group median (the Brown–Forsythe form), which stays reliable on skewed data; Bartlett's test is more powerful but only trustworthy when the data are normal. A significant p means the equal-variance assumption fails — prefer Welch's t-test or a rank-based test.
| Test | Statistic | p | Largest / smallest variance | Verdict |
|---|---|---|---|---|
| Levene (Brown–Forsythe, median-centred) | 0.7282 | 0.51 | 2.34 | Homogeneous |
| Bartlett | 0.4614 | 0.79 | 2.34 | Homogeneous |
LabTools calls (2)
stats.levenelabtools stats levene --groups @groups.json --method levene
stats.levenelabtools stats levene --groups @groups.json --method bartlett
The same method is available as an MCP tool (stats_levene) and from the desktop app's statistics panel.
LabTools notes
- Group 'Regimen A' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
- Group 'Regimen B' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
- Group 'Regimen C' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
- Non-significant. This test has low power on small samples, so treat this as 'no evidence against equal variances', not as evidence for them.
- Bartlett's test assumes normality and is badly inflated when that fails — confirm with stats.normality, or use method='levene'.
Outlier screen
Five detectors with different assumptions. Grubbs tests the single most extreme point, generalised ESD looks for up to several (immune to masking), Dixon's Q is the small-sample chemistry test, modified-z uses the median and MAD so needs no normality, and the IQR rule is Tukey's boxplot fence. LabTools flags points; it never deletes them.
| Method | Regimen A | Regimen B | Regimen C |
|---|---|---|---|
| Grubbs | none | none | none |
| Generalised ESD | none | none | none |
| Dixon's Q | none | none | none |
| Modified z (MAD) | none | none | 1 (57) |
| IQR fences (1.5×) | none | none | 1 (57) |
LabTools calls (5)
stats.outlierslabtools stats outliers --groups @groups.json --method grubbs
stats.outlierslabtools stats outliers --groups @groups.json --method generalized-esd --max-outliers 1
stats.outlierslabtools stats outliers --groups @groups.json --method dixon-q
stats.outlierslabtools stats outliers --groups @groups.json --method modified-z
stats.outlierslabtools stats outliers --groups @groups.json --method iqr
The same method is available as an MCP tool (stats_outliers) and from the desktop app's statistics panel.
LabTools notes
- Flagged points are candidates, not verdicts, and nothing has been removed. Look for a physical cause before excluding anything; if there is none, keep the point and use a robust test instead. Any exclusion must be reported.
- The IQR rule is descriptive — it has no p-value and flags roughly 0.7% of a perfectly normal sample by construction.
Confidence intervals for the mean
t-based intervals: the range of population means these data are consistent with. Report them alongside p-values — an interval shows the size of an effect, a p-value does not.
| Group | n | Mean | 95% CI |
|---|---|---|---|
| Regimen A | 4 | 30 | [26.56, 33.44] |
| Regimen B | 4 | 39.25 | [33.99, 44.51] |
| Regimen C | 4 | 53 | [48.69, 57.31] |
LabTools calls (2)
stats.cilabtools stats ci --data @Regimen_A.json --conf-level 0.95
stats.cilabtools stats ci --data @Regimen_C.json --conf-level 0.95
The same method is available as an MCP tool (stats_ci) and from the desktop app's statistics panel.
Do the groups differ? (omnibus tests)
One-way ANOVA compares means and assumes normal residuals with equal variances; Kruskal–Wallis compares ranks and assumes neither. Both only say the groups differ somewhere — the pairwise table below says where.
| Test | Statistic | df | p | Effect size |
|---|---|---|---|---|
| One-way ANOVA | F = 70.13 | 2, 9 | 3.2 × 10⁻⁶ | ω² = 0.92 · η² = 0.94 · Cohen's f = 3.95 |
| Kruskal–Wallis H | H = 9.881 | 2 | 0.007 | ε² = 0.898 |
LabTools calls (2)
stats.anovalabtools stats anova --groups @groups.json
stats.kruskallabtools stats kruskal --groups @groups.json
The same method is available as an MCP tool (stats_anova) and from the desktop app's statistics panel.
LabTools notes
- Group 'Regimen A' has n = 4; normality screening has very low power at this size, so a non-significant Shapiro–Wilk is weak evidence of normality.
Which groups differ? (pairwise, corrected)
3 comparisons (every pair), each run as a Welch t-test and a Mann–Whitney test. Testing many pairs inflates false positives, so every p-value is corrected with Holm (family-wise) and Benjamini–Hochberg (false-discovery rate) through stats.adjust.
| Comparison | Mean diff. | 95% CI | Hedges' g | Welch p | Holm | BH | Mann–Whitney p | Holm | Cliff's δ |
|---|---|---|---|---|---|---|---|---|---|
| Regimen A vs Regimen B | -9.25 | [-14.27, -4.226] | -2.88 | 0.005 | 0.005 | 0.005 | 0.030 | 0.088 | -1 |
| Regimen A vs Regimen C | -23 | [-27.29, -18.71] | -8.16 | 1.6 × 10⁻⁵ | 4.9 × 10⁻⁵ | 4.9 × 10⁻⁵ | 0.029 | 0.088 | -1 |
| Regimen B vs Regimen C | -13.75 | [-19.03, -8.474] | -3.96 | 0.0008 | 0.002 | 0.001 | 0.029 | 0.088 | -1 |
LabTools calls (3)
stats.ttestlabtools stats ttest --a @Regimen_A.json --b @Regimen_B.json --test welch --no-assumption-checks
stats.mannwhitneylabtools stats mannwhitney --a @Regimen_A.json --b @Regimen_B.json
stats.adjustlabtools stats adjust --p-values @p_values.json --labels @labels.json --method holm
The same method is available as an MCP tool (stats_ttest) and from the desktop app's statistics panel.
Design sensitivity
LabTools calls (2)
stats.powerlabtools stats power --n1 4 --n2 4 --mode mde --power 0.8
stats.powerlabtools stats power --n1 4 --n2 4 --effect-size 0.5
The same method is available as an MCP tool (stats_power) and from the desktop app's statistics panel.
Methods paragraph
Written to go straight into a manuscript.
Mean dosing duration was 30.0 ± 2.2 days for Regimen A, 39.3 ± 3.3 days for Regimen B and 53.0 ± 2.7 days for Regimen C (mean ± SD, n = 4 each).
Every number on this page was computed by the LabTools statistics engine (version 0.14.3) from the example's CSV on 2026-09-23. Where a value was derived before the data reached LabTools (replicate means, paired differences, log odds ratios), the text says so. The data are simulated from a fixed random seed.
Get started
Run the same analysis on your data
Every test on this page is built into LabTools — from the statistics panel, the command line, or an AI assistant through MCP.